Anthropic's revised Usage Policy takes effect on November 12. For teams building with Claude, its most important change is not a new list of forbidden prompts. It is a clearer description of the controls that must surround an AI system when outputs can affect a person or move equipment.
The policy applies broadly. Anthropic says it covers people using its apps, developers and businesses using its API, customers accessing Claude through cloud providers and authorized resellers, and end users of products that integrate Claude. That makes this a deployment issue, not only a procurement or prompt-design issue.
The deadline is a useful forcing function. Operators should be able to identify which workflows fall into Anthropic's high-risk categories, where accountable review happens, how an affected person is informed, whether physical systems can fail safely, and which regions every user and related entity operates from.
This is an analysis of Anthropic's platform policy, not legal advice. Local laws and contracts can impose separate or stricter duties.
The policy separates three kinds of control
The revised policy has three layers: universal prohibitions, requirements for high-risk use cases, and additional guidelines for specific products such as consumer-facing agents. That structure matters because a team cannot solve every obligation with the same moderation filter.
Universal standards prohibit uses including unauthorized computer access, weapons development, deceptive campaigns, certain surveillance, fraud, and model distillation without permission. High-risk requirements govern otherwise permitted systems whose recommendations or physical actions could materially affect people. Additional guidelines apply to product patterns such as chatbots and agents.
The operating question is therefore not simply whether a use case is allowed. It is which layer applies and what evidence shows the required control is present.
Human review must sit before the consequential output
Anthropic defines eleven areas of high-risk recommendation, including legal, medical, finance, credit, insurance, housing, employment, education, healthcare access, public benefits, and legal status. When Claude produces a recommendation in one of those areas, a qualified person must meaningfully review it and have authority to change it before the advice reaches an individual or a decision is implemented.
That sequence is architectural. A general approval log created after delivery does not satisfy the stated flow. The reviewer needs the relevant output, enough context to assess it, and an actual control that can stop or modify the result.
The policy also requires the person receiving advice, or subject to a decision, to be clearly told that AI was used. Anthropic does not require that notice to name Claude or Anthropic. Teams should still treat the notice as a product state that can be tested, localized, versioned, and preserved with the decision record.
There are useful boundaries. General education, internal research or drafting that is not the ultimate recommendation, fixed rules with no model judgment, and business operations that do not advise or decide about a specific person are among the listed exclusions. The policy also lists a narrow human-review exception for certain wholly favorable insurance, healthcare-access, or public-benefit decisions where law permits, while noting that disclosure duties may still apply. The distinction turns on what the output does in the workflow, not the department that owns it.
Physical agents need an independent safety layer
The most concrete new obligations concern models connected to hardware. Anthropic's requirements apply when model output acts without human approval and equipment can move through shared space, apply injurious force, control hazardous energy or materials, act on a body, control safety systems, or run an industrial process that could harm people.
A qualified individual must be able to observe the equipment and stop it at any time. The equipment must also stop or hold a safe state when the operator intervenes or the connection to Anthropic is lost.
Crucially, operating limits such as speed, force, temperature, voltage, dose, or working area must be enforced by the equipment or a controller independent of model output. A model prompt saying "stay within safe limits" is not an independent limit.
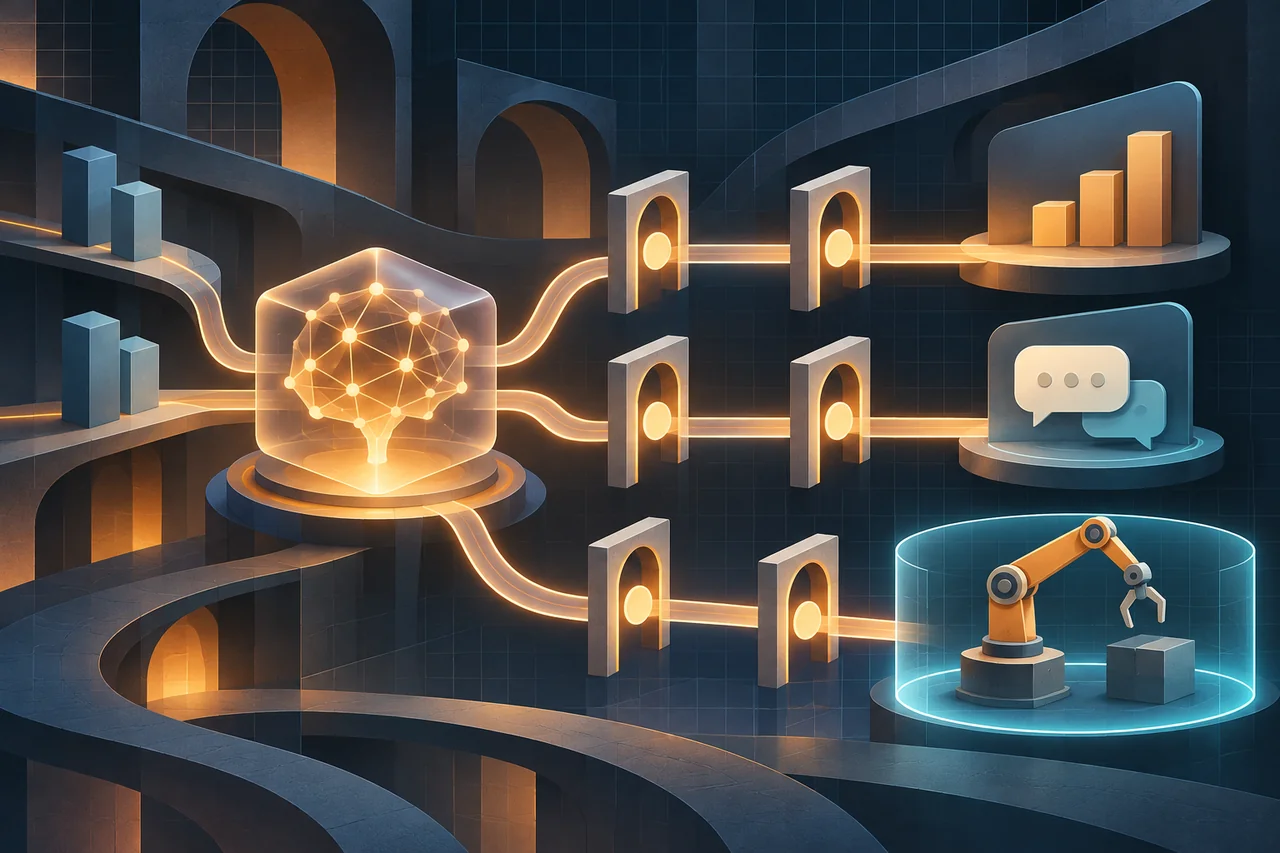
This creates a clean engineering principle: the model may propose or direct, but it must not be the sole keeper of the safety envelope. Teams building robotics and other physical agents should map every hazardous degree of freedom to a deterministic interlock, controller, or certified subsystem outside the model's authority.
Consumer agents need visible identity and bounded tools
All consumer-facing chatbots or agents that communicate directly with external users must disclose that the user is interacting with AI rather than a human. Anthropic says the disclosure must appear at least at the beginning of each session or in the product interface.
The policy separately says teams are responsible for actions their agents take through tools, browsers, or connected systems. That closes an easy governance gap. A compliant model response is not enough if an agent can use a tool to perform a prohibited action or bypass a required review.
Tool permissions should therefore reflect the policy classification. A research agent may be allowed to gather and summarize evidence, while the action that delivers individualized advice, changes employment status, releases funds, or moves machinery should cross a separately controlled boundary.
Our field guide to production agents makes the broader case for separating mission, state, tools, authority, verification, and operations. Anthropic's policy gives that architecture a vendor-specific test: can the system prove who reviewed what, what the user saw, which tool acted, and which independent control could stop it?
Region checks now reach ownership and travel
Anthropic's revised Supported Regions Policy also takes effect November 12. It applies not only to where a person is physically located, but also to where an entity is incorporated or headquartered and whether it is majority-owned or controlled by persons or entities in unsupported regions.
For global organizations, a billing address check is too narrow. Access controls may need to consider personnel travel, contractor location, subsidiaries, ownership, cloud marketplace access, and end users of an integrated product. The policy says personnel of an otherwise supported entity cannot use the service while physically in an unsupported region.
A readiness review for November 12
Teams using Claude can turn the policy into a short evidence-based review:
- Inventory: list Claude deployments, including cloud-provider access, embedded products, internal agents, and physical systems.
- Classify: map each workflow to universal prohibitions, high-risk recommendations, physical actions, and additional product guidelines.
- Place controls: put qualified review before consequential delivery or action, and keep hardware safety limits outside model control.
- Make disclosure testable: verify that affected people and consumer chat users see the required notice at the right time.
- Constrain tools: ensure browsers, APIs, and connected systems cannot route around policy gates.
- Check regions: validate physical location, entity location, ownership, and downstream access paths against the supported list.
- Retain evidence: preserve the classification, reviewer action, disclosure version, tool event, and safety-control test that support each deployment.
Make provider policy a versioned control layer
Anthropic is not the only provider attaching near-term operating requirements to model access. OpenAI's revised Usage Policies take effect November 20. They also prohibit automating high-stakes actions without human review, but add a different infrastructure concern: OpenAI says services that provide direct access to its models, including model routers and AI gateways, must obtain its review and approval before offering that access.
OpenAI also says it is working with customers on SafetyIDs, identifiers intended to distinguish end users during misuse investigations without revealing their identities to OpenAI. That creates a design question for platforms serving multiple customers: can an incident be narrowed to one actor without sharing unnecessary personal data or disrupting every tenant?
The practical pattern is to keep a provider-policy matrix beside the deployment inventory. Map each model route to its effective policy version, approval requirements, high-stakes review gate, user-notice state, safety identifier, region rules, and owner. Then test the control at the gateway and action boundary. A single generic "responsible use" prompt cannot represent these differences or prove which policy applied when an event occurred.
The broader lesson is durable beyond one provider. As agents gain longer-running tools and physical reach, governance is becoming part of system design. The teams best prepared for policy changes will be the ones that can change a control once, show where it applies, and prove that the workflow cannot silently route around it.
- Anthropic: 2026 Usage Policy update
- Anthropic: Usage Policy effective November 12, 2026
- Anthropic: Supported Regions Policy effective November 12, 2026
- Anthropic: Model Hardware Standard research preview
- OpenAI: Broad access through consistent standards
- OpenAI: Usage Policies effective November 20, 2026